CEO Bench Shows Why Long-Horizon Business Agents Still Need Human Control
A practical evaluation guide for CEO Bench, focused on long-horizon agent evaluation, operating boundaries, failure behavior, and production readiness.
5 min
共 151 篇文章
A practical evaluation guide for CEO Bench, focused on long-horizon agent evaluation, operating boundaries, failure behavior, and production readiness.
A product-operations view of AI-Locust: the framework matters because it turns benchmark execution into durable, reviewable, repeatable assets.
A product-operations view of OpenTag: the value is owning context, approvals, runtime, and model choice.
The product signal is not “free CapCut,” but an editor that agents and creators can automate.
A product-operations reading: OpenAI needs custom inference economics more than a headline Nvidia rivalry.
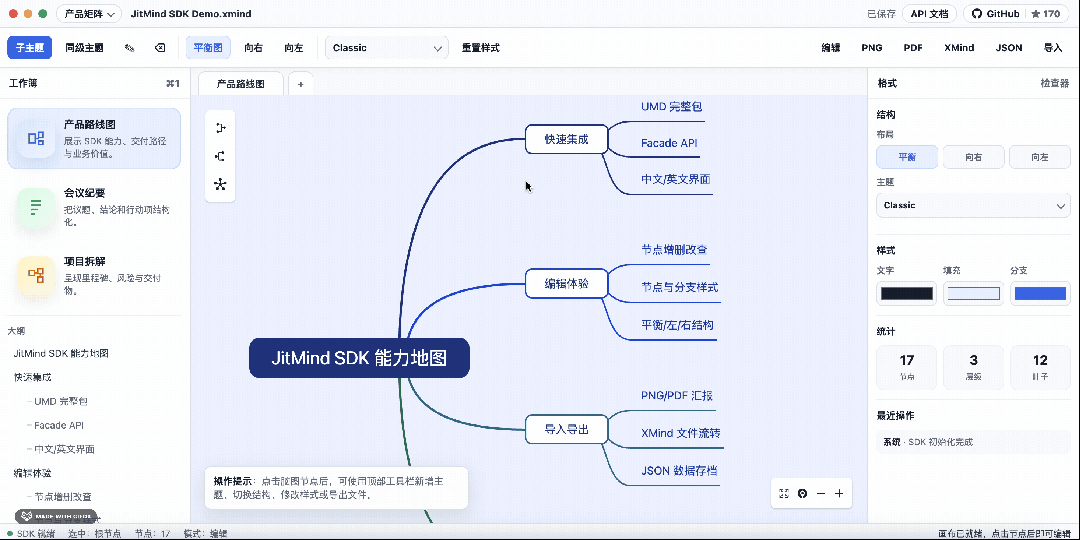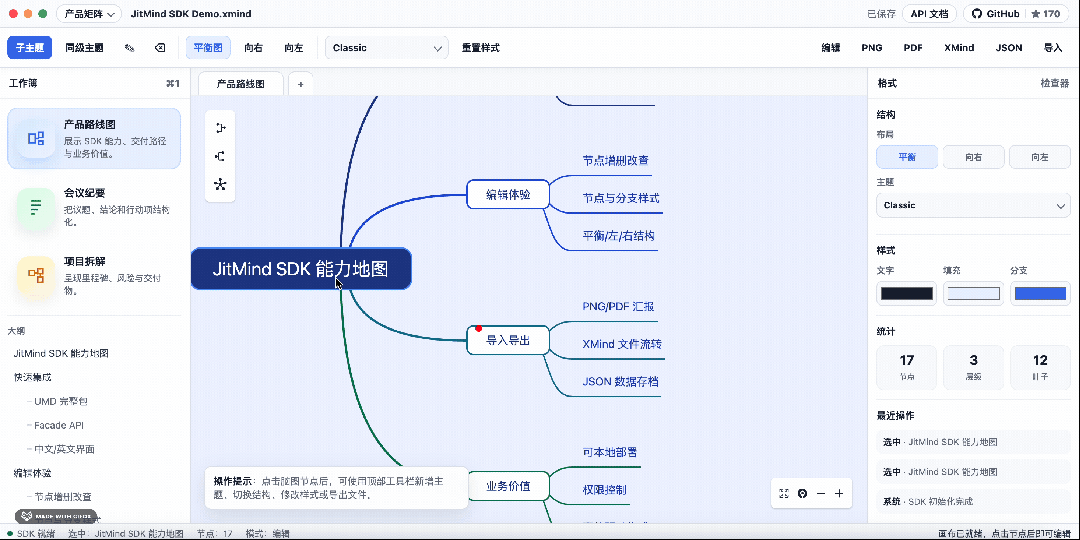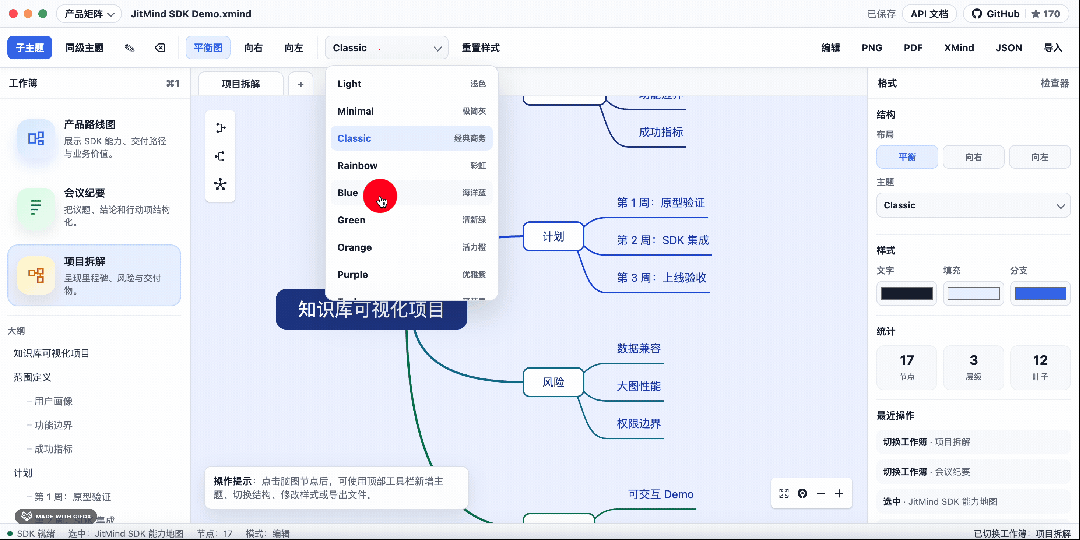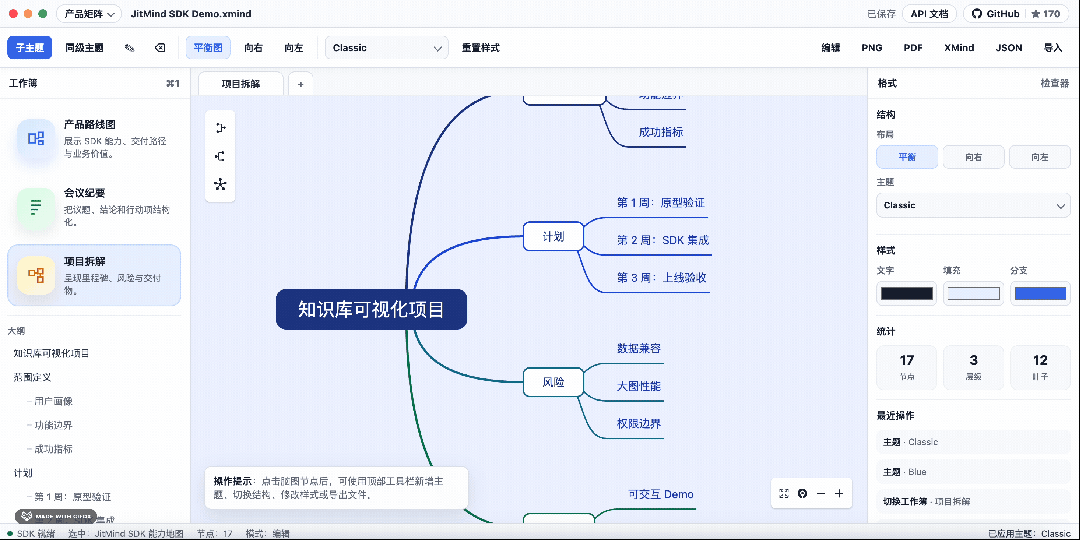
JitWord’s SDK shows how knowledge-structure editing can move from desktop tools into product workflows, AI documents, and team systems.
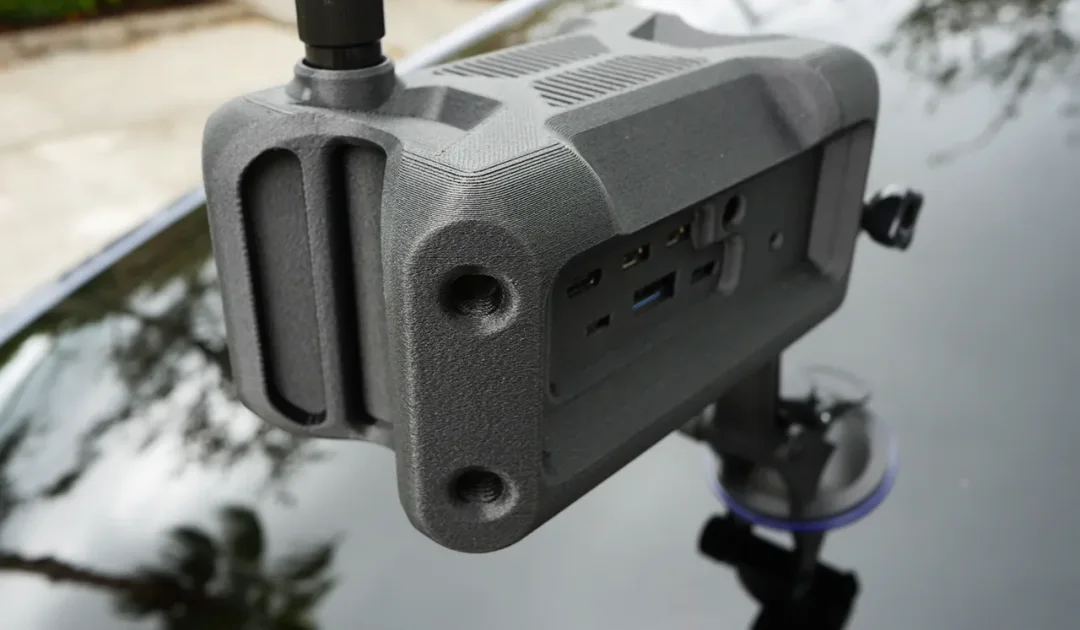
A product-operations look at Haven: low-cost IP mesh can support disaster response, off-grid communities, and field teams.
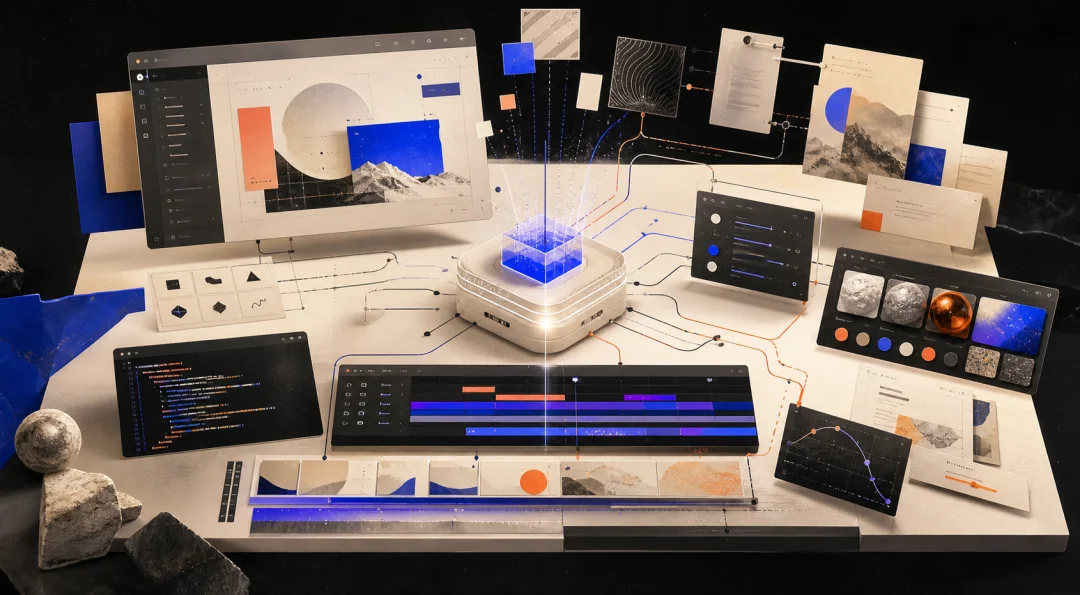
The important change is not prettier generated screens, but reusable tools built from team context and design judgment.
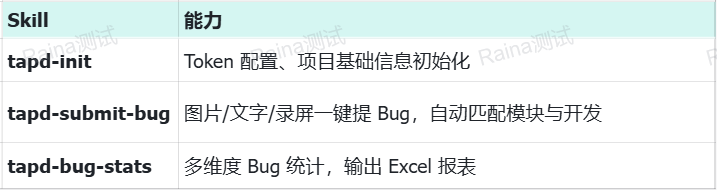
The value is not a generic Jira bot, but a governed skill chain for submission, confirmation, and statistics.
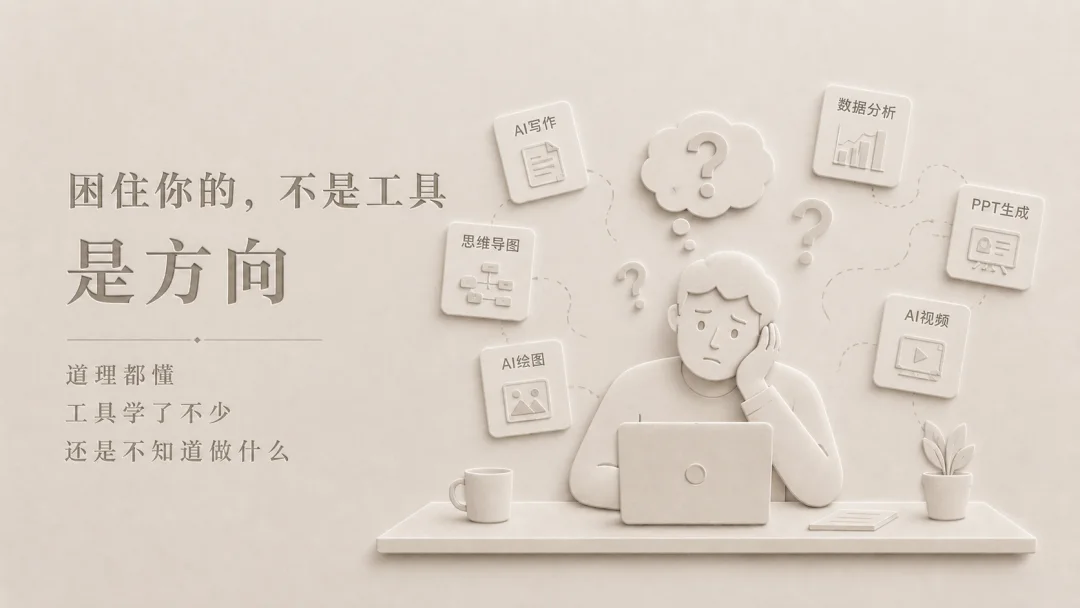
A pragmatic view: tools matter only after a person has a real problem, audience, and repeatable delivery path.
A practical evaluation guide for Java logging, focused on choosing Logback or Log4j2 for production services, operating boundaries, failure behavior, and production readiness.
A practical evaluation guide for D2, focused on diagram-as-code documentation, operating boundaries, failure behavior, and production readiness.
A practical evaluation guide for ByteChef, focused on AI workflow automation, operating boundaries, failure behavior, and production readiness.
A product-operations view of Flutter: the real gain is reducing multi-platform delivery drag, not pretending one codebase removes all platform work.
A practical evaluation guide for Apache Tika in Spring Boot, focused on document ingestion services, operating boundaries, failure behavior, and production readiness.
Teams are not rejecting modularity. They are rejecting a deployment model that turns every feature into distributed operations overhead.
A practical evaluation guide for Mistral OCR 4, focused on structured document AI, operating boundaries, failure behavior, and production readiness.
A practical evaluation guide for Claude Code commands, focused on repeatable coding-agent workflows, operating boundaries, failure behavior, and production readiness.
A practical evaluation guide for all-POST API design, focused on API style decisions, operating boundaries, failure behavior, and production readiness.
MoA should be used as an escalation path for risky agent work, not as the default way to make every answer longer.